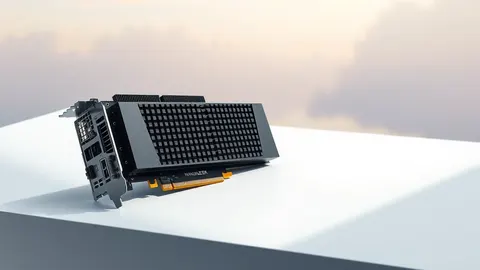
Intel names Crescent Island AI accelerator the GPU D-Series with 1.3 PFLOPS FP8
Intel officially brands its Crescent Island inference chip as the GPU D-Series, targeting air-cooled rack deployments with up to 480GB of high-bandwidth memory.
Key points
- The GPU D-Series delivers a theoretical peak of 1.3 PFLOPS of FP8 compute performance.
- Chips feature up to 480 GB of LPDDR5X memory providing 1.5 TB/s of bandwidth.
- Products are designed for air-cooled PCIe form factors with a 350W thermal design power.
Intel officially named its Crescent Island AI inference accelerator the GPU D-Series during the Open Compute Project 2026 event. The company revealed specific performance targets for the new hardware family, marking a shift from earlier speculative disclosures about the chip’s capabilities and architecture throughout the year.
The GPU D-Series chips are built on Intel’s Xe3P graphics architecture, which the company describes as a massively parallel computing design rather than a traditional graphics processor. According to Tom’s Hardware, the chips lack most graphics-specific functional units, focusing instead on AI inference tasks. Intel stated that the products will arrive in an air-cooled PCIe form factor with a thermal design power of 350 watts.
Technical Specifications and Performance Targets
Intel disclosed that the GPU D-Series will offer up to 480 GB of LPDDR5X memory, delivering 1.5 TB/s of memory bandwidth. The theoretical peak performance for the chip is set at 1.3 PFLOPS of FP8 compute throughput. These specifications define the hardware’s capacity for handling large-scale data processing tasks in enterprise environments.
The performance envelope of the GPU D-Series differs significantly from high-end competitors like Nvidia’s Vera Rubin NVL72 system. While each Rubin GPU can theoretically reach 17.5 PFLOPS of FP8 throughput, those chips require liquid cooling and likely consume kilowatts of power. In contrast, the Intel chips are designed for standard data center infrastructure.
Deployment and Software Ecosystem
Intel intends for the GPU D-Series to be deployed in traditional air-cooled rack servers, scaling up to eight GPUs per system. This configuration allows the hardware to power inference on models with more than one trillion parameters. The company highlights suitability for large language models, long-context inference, and concurrent inference services.
To support distributed inference across multiple GPUs, Intel is leveraging its common Xe software foundation. This software stack is already used for AI across Intel’s Xe Cores in integrated and discrete GPU products. The company aims to create a foundation for multi-tenant AI services, robotics, and other latency-sensitive workloads.
Industry Partners and Availability
Intel stated it is working with a broad ecosystem of partners to bring Xe accelerators into the data center. These partners include original equipment manufacturers, original design manufacturers, neoclouds, independent software vendors, appliance providers, and AI-native companies. Customer sampling of GPU D-Series products is currently in progress.
The company did not provide details regarding a broad commercial launch date or specific pricing for the hardware. The focus remains on the technical specifications and the ecosystem partnerships that will support the deployment of these inference-optimized accelerators in enterprise settings.
What should you do?
Security and technology professionals should monitor Intel’s official channels for final technical documentation and security advisories related to the GPU D-Series. As customer sampling begins, organizations should evaluate the hardware’s compatibility with existing air-cooled rack infrastructure. Teams should also review the common Xe software foundation for any required updates to their current AI inference pipelines.
Background: Large language models
Large language models are a specific type of neural network trained on text. Generative AI is the broader umbrella term for any system that creates new content, including images and code. Not all generative AI uses large language models, but most modern text generators do.
What to do and how to stay safe: Intel
- Verify that your data center’s power and cooling infrastructure can support 350W PCIe cards without requiring liquid cooling upgrades.
- Review the common Xe software foundation documentation to ensure compatibility with your current AI inference workloads and large language models.
- Monitor Intel’s official security bulletins for any vulnerabilities disclosed during the customer sampling phase of the GPU D-Series.
- Assess whether the 1.5 TB/s memory bandwidth meets the requirements for your specific latency-sensitive AI services and robotics applications.
Step-by-step guide: Prompt Injection Warning Signs: How to Spot AI Manipulation
General security guidance from the Threat Times newsroom. It is not confirmed advice from the organisations named in this story.
Frequently asked questions
What is the peak performance of the Intel GPU D-Series?
The GPU D-Series has a theoretical peak performance of 1.3 PFLOPS of FP8 compute.
How much memory do the GPU D-Series chips support?
The chips support up to 480 GB of LPDDR5X memory with 1.5 TB/s of bandwidth.
When will the GPU D-Series be available for purchase?
Customer sampling is in progress, but Intel has not announced a broad launch date.